AI Inference: One Rack or Many Servers? Design study of a bank
Six ways to serve a bank's AI models; three racks meet it. We supply and integrate what passed.
AI Inference: One Rack or Many Servers? Design study of a bank
Six ways to serve a bank's AI models; three racks meet it. We supply and integrate what passed.
Six AI systems from makers we carry, held to one requirement from our design study of a bank, not a client. Its four clauses are in the buyer's voice and name no product.
No request or response leaves the bank's hall. The largest model runs whole in one GPU memory domain of at least 20 TB. Each rack stays within 142 kW on the hall's facility water. Each GPU has its own network link of at least 800 Gb/s. One supplier supports hardware and software as one case.
Every source is a public page you can open yourself.¹ Anything inferred is marked.
On the public record: a US court ordered OpenAI to preserve output log data that would otherwise be deleted (May 2025); the duty ended by agreement in September 2025, with exceptions. OpenAI is not our client. This requirement keeps every request and response inside the hall.
1. Six systems, one requirement
Six systems were assessed. Three are GB300 NVL72 racks, from Dell, HPE and NVIDIA. Two are eight-GPU servers, from Cisco on NVIDIA HGX B300 and from Dell on AMD Instinct MI355X. The sixth is NVIDIA's next rack, Vera Rubin NVL72.²
AWS, Google Cloud and Equinix were set aside at the first question, because inference would leave the bank's hall.
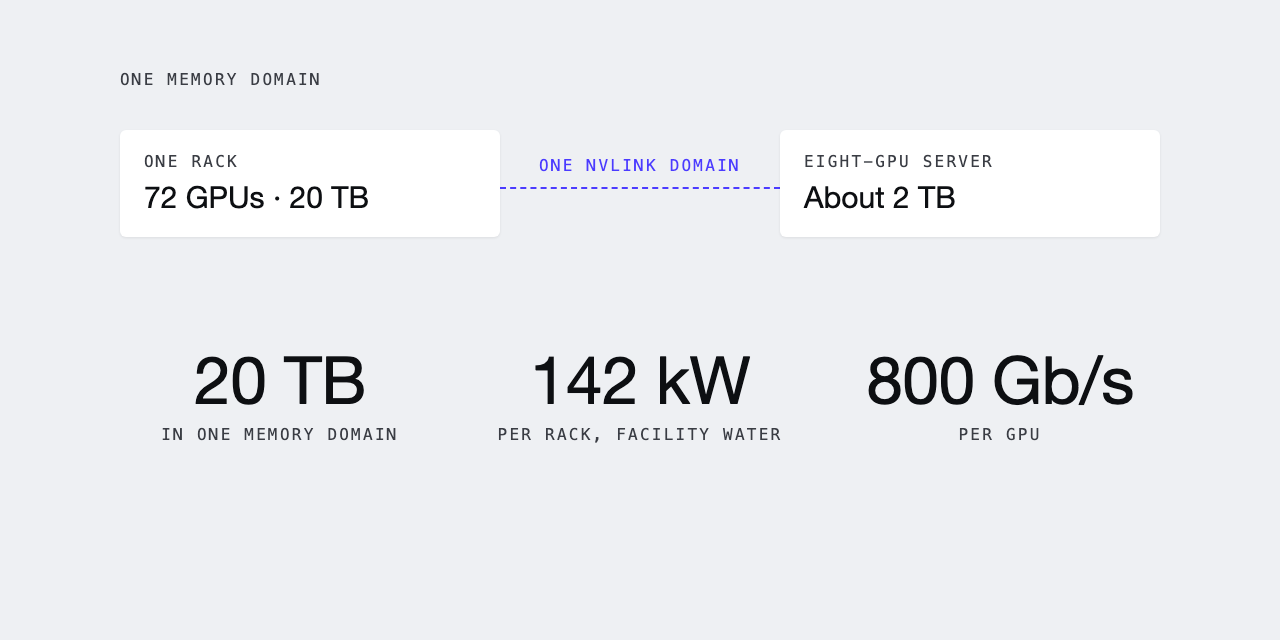
One memory domain of at least 20 TB, inside the bank's own hall.
2. Three racks meet the requirement.
Three racks meet the requirement, each once a named condition is settled at the quote. Dell, its network module and support hours. HPE, longer software support on the order. NVIDIA DGX, its support hours.
The two eight-GPU servers are set aside on memory: about 2 TB per server against the 20 TB the largest model needs. Vera Rubin NVL72 meets the memory clause, but NVIDIA's datasheet rates the rack at 156 to 227 kW, above the 142 kW this hall allows, so it does not go on to price.³
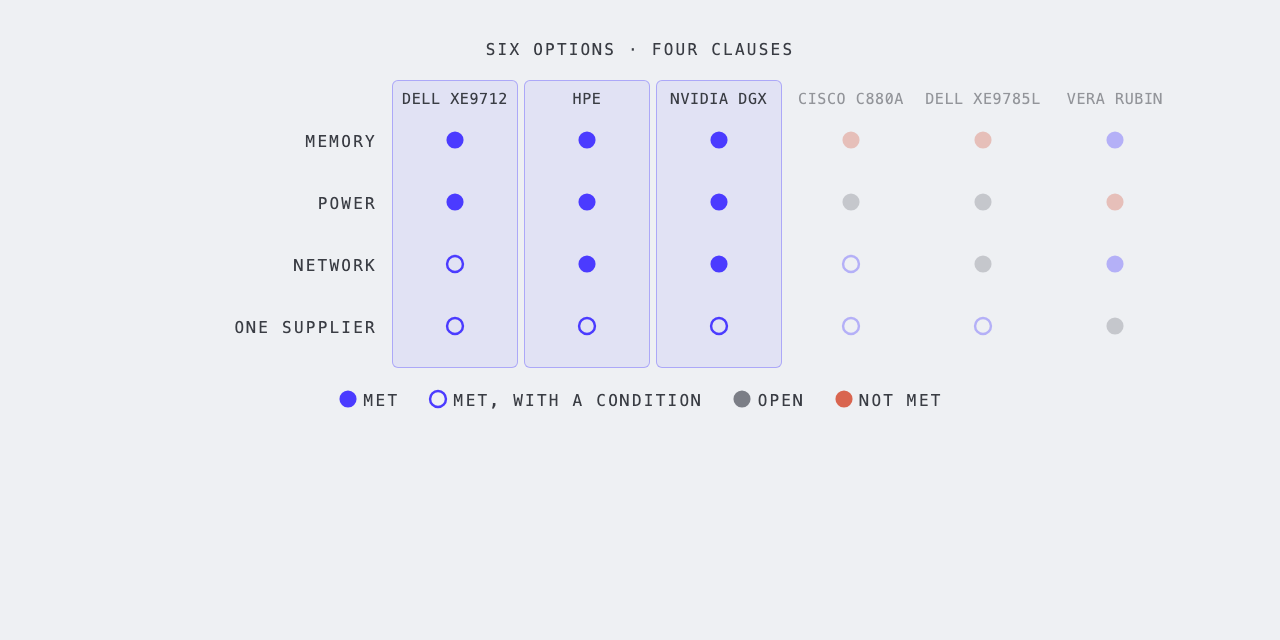
3. Price does not rank the three
Price is weighed only among the three racks that met every line. They are not ranked, and no price figure is published. The buyer's quote for the same racks, networking and support decides between them.
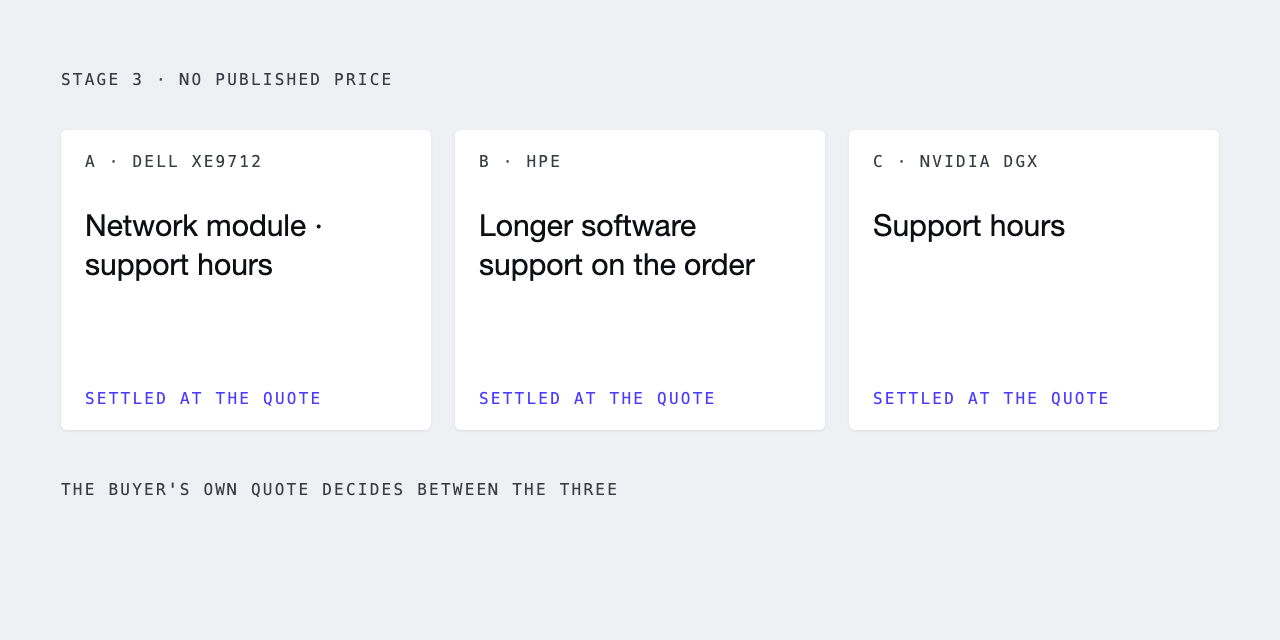
Three racks meet it. The buyer's quote decides between them.
4. We recommend all three racks that met every line
One rack, not many servers. We recommend the three GB300 NVL72 racks that met every line, from Dell, HPE and NVIDIA, and your quote decides between them. We supply and integrate all three: ask us for that quote.
What splits this field is memory: at least 20 TB in one rack's memory domain, against about 2 TB in an eight-GPU server.
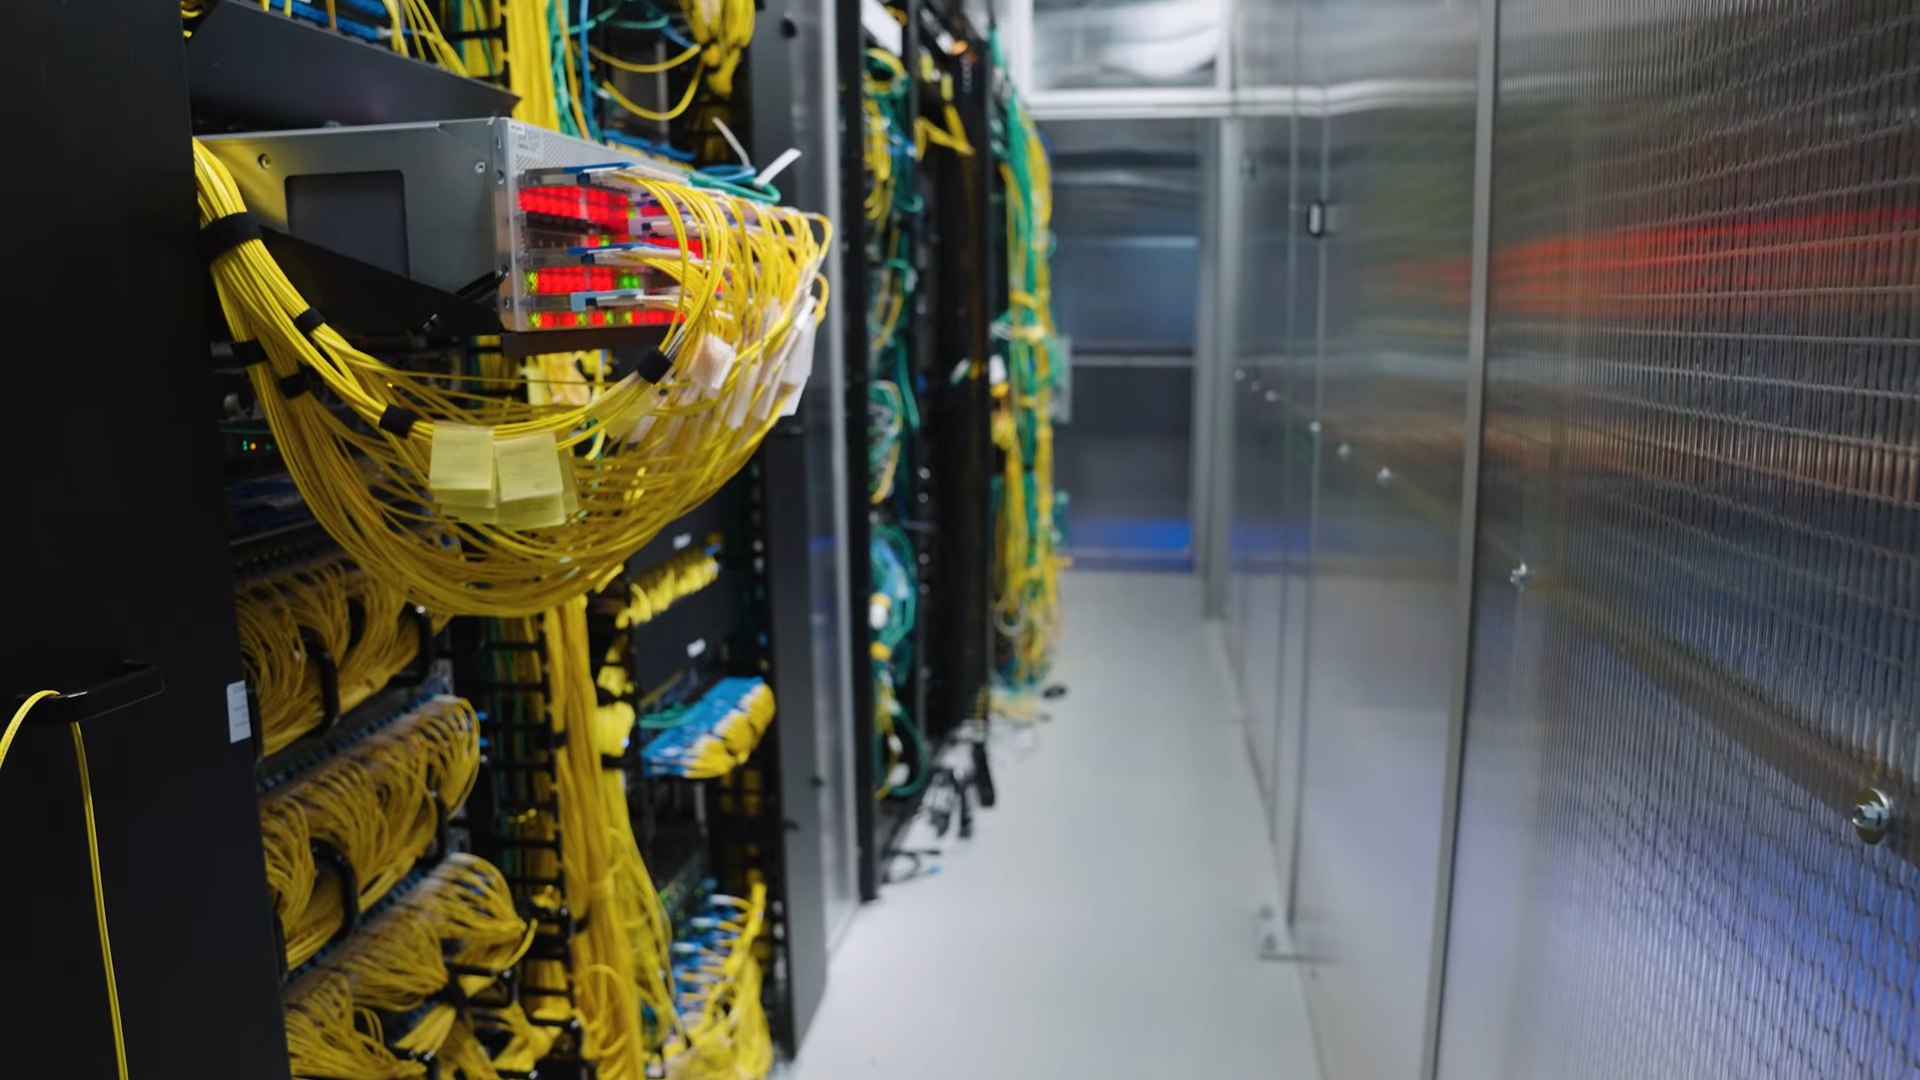
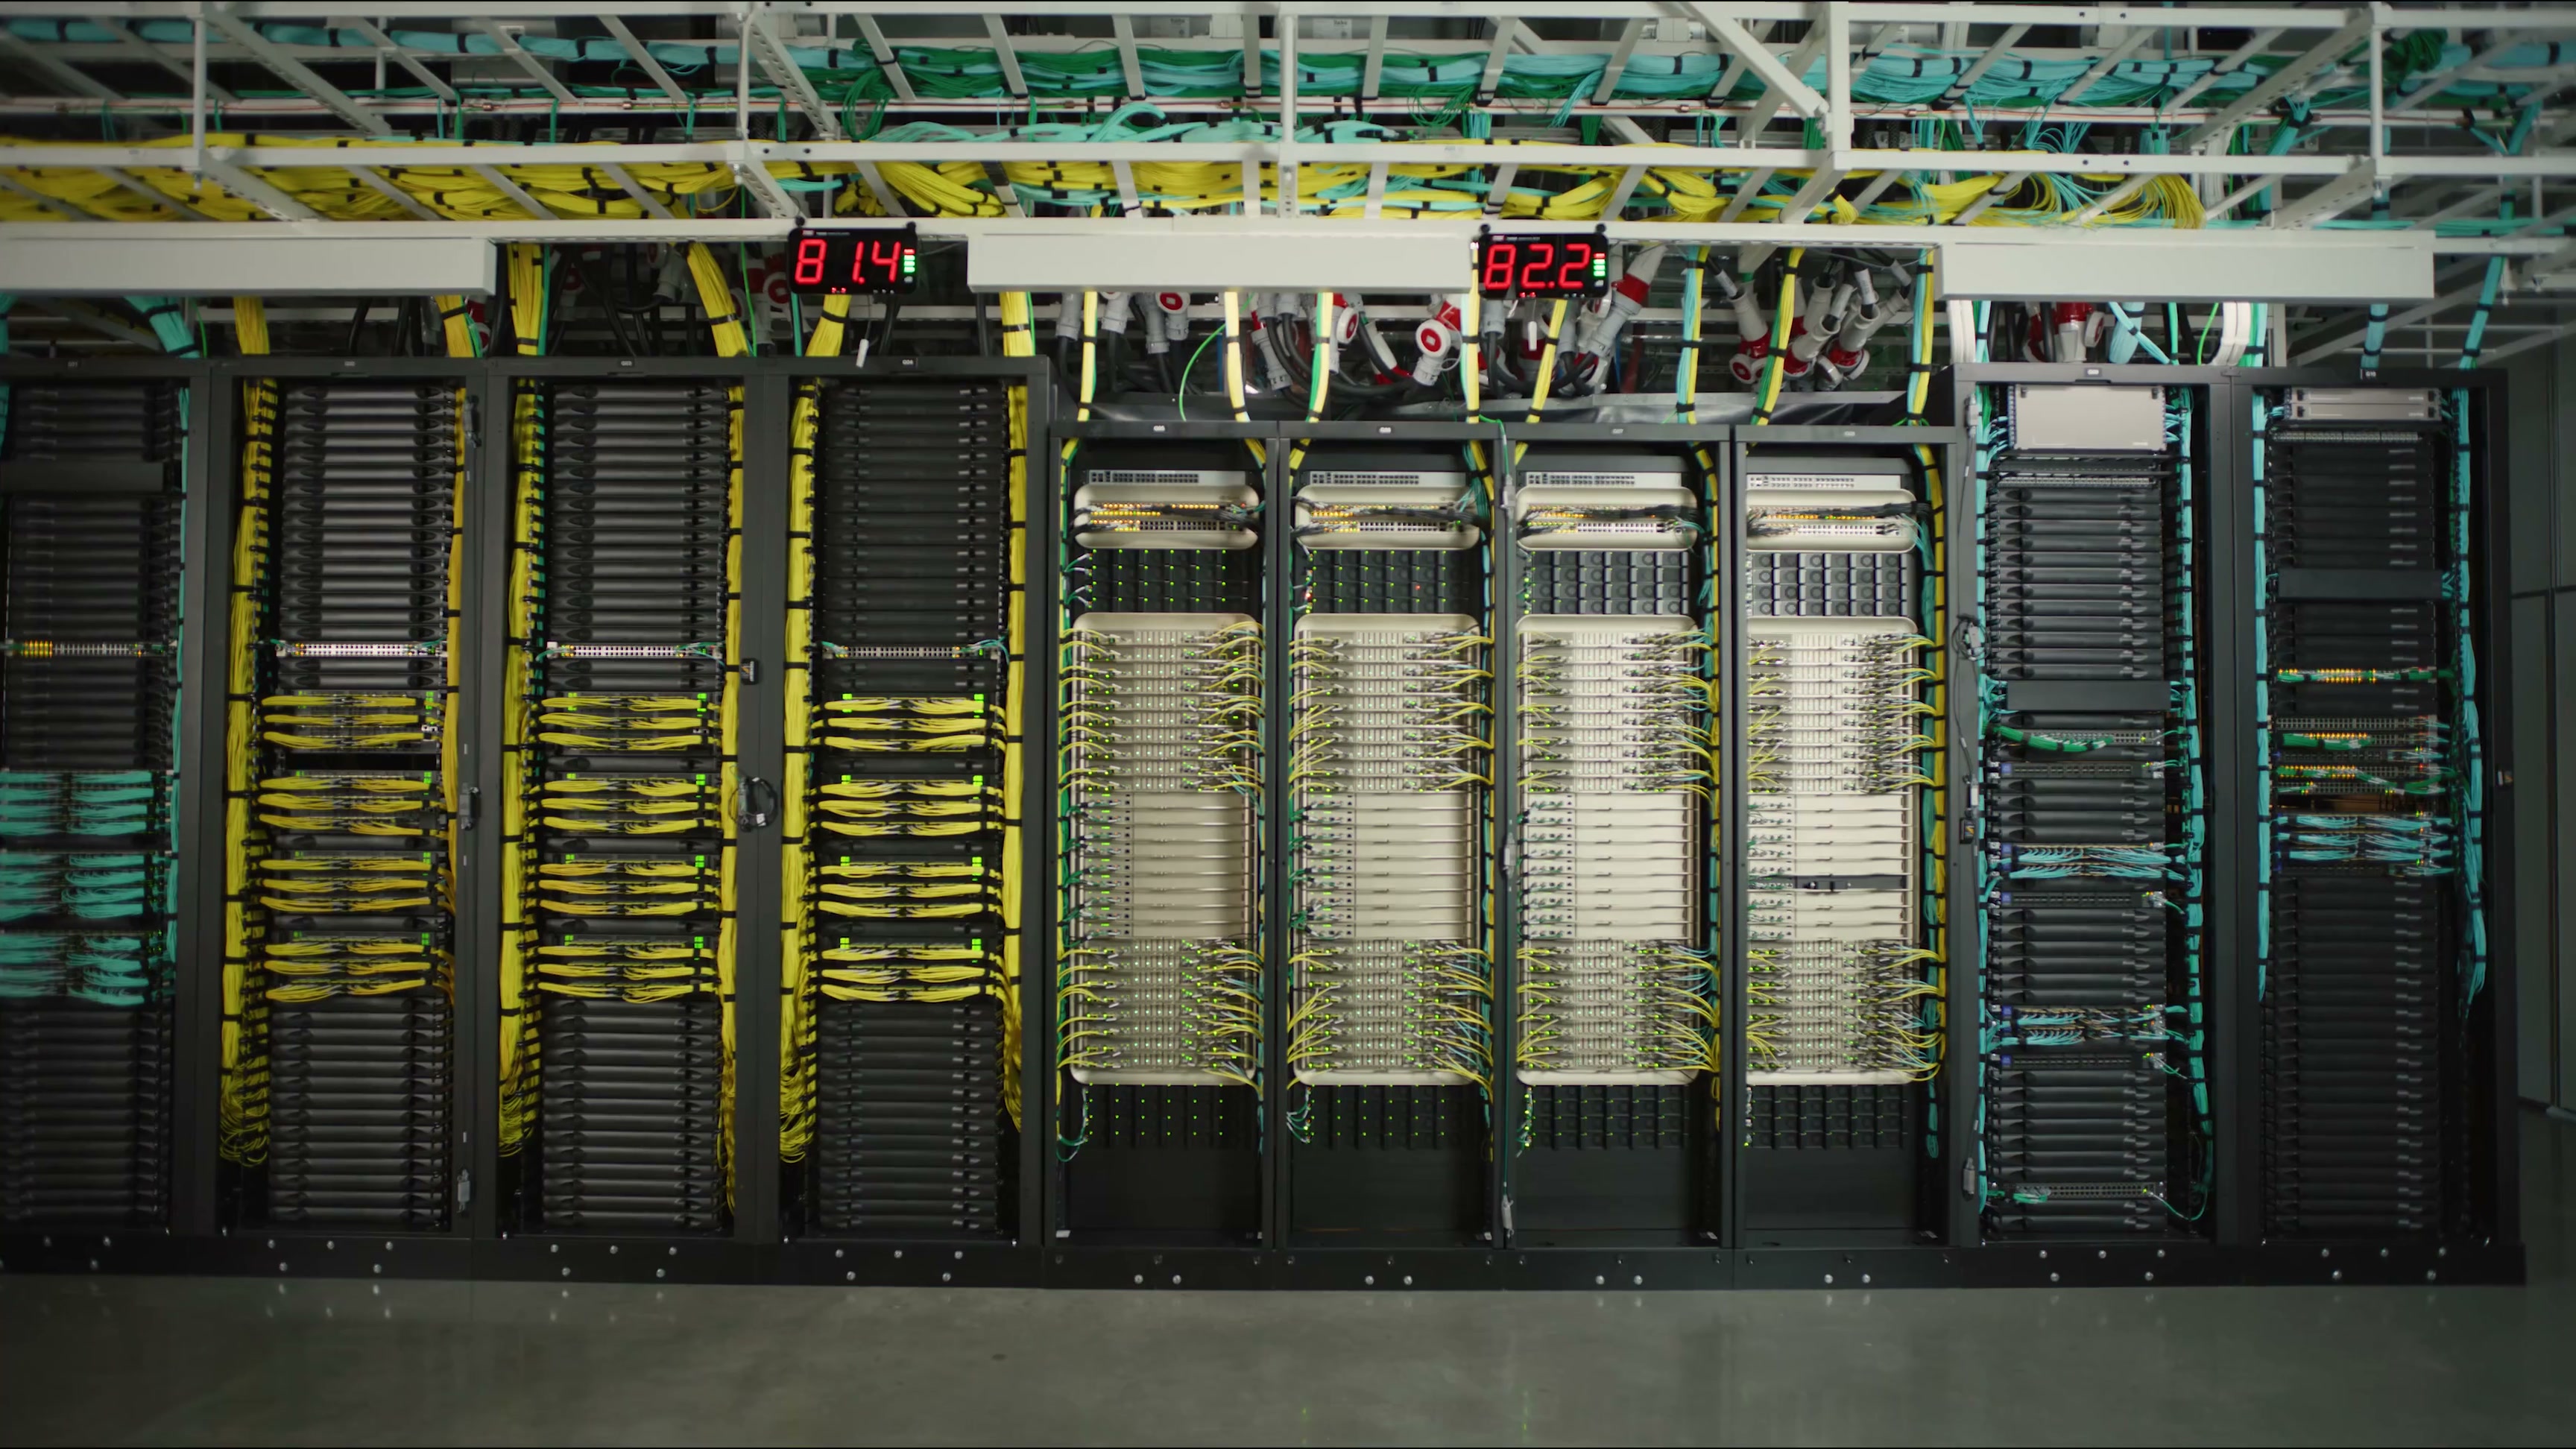
A data-hall aisle with yellow fiber.
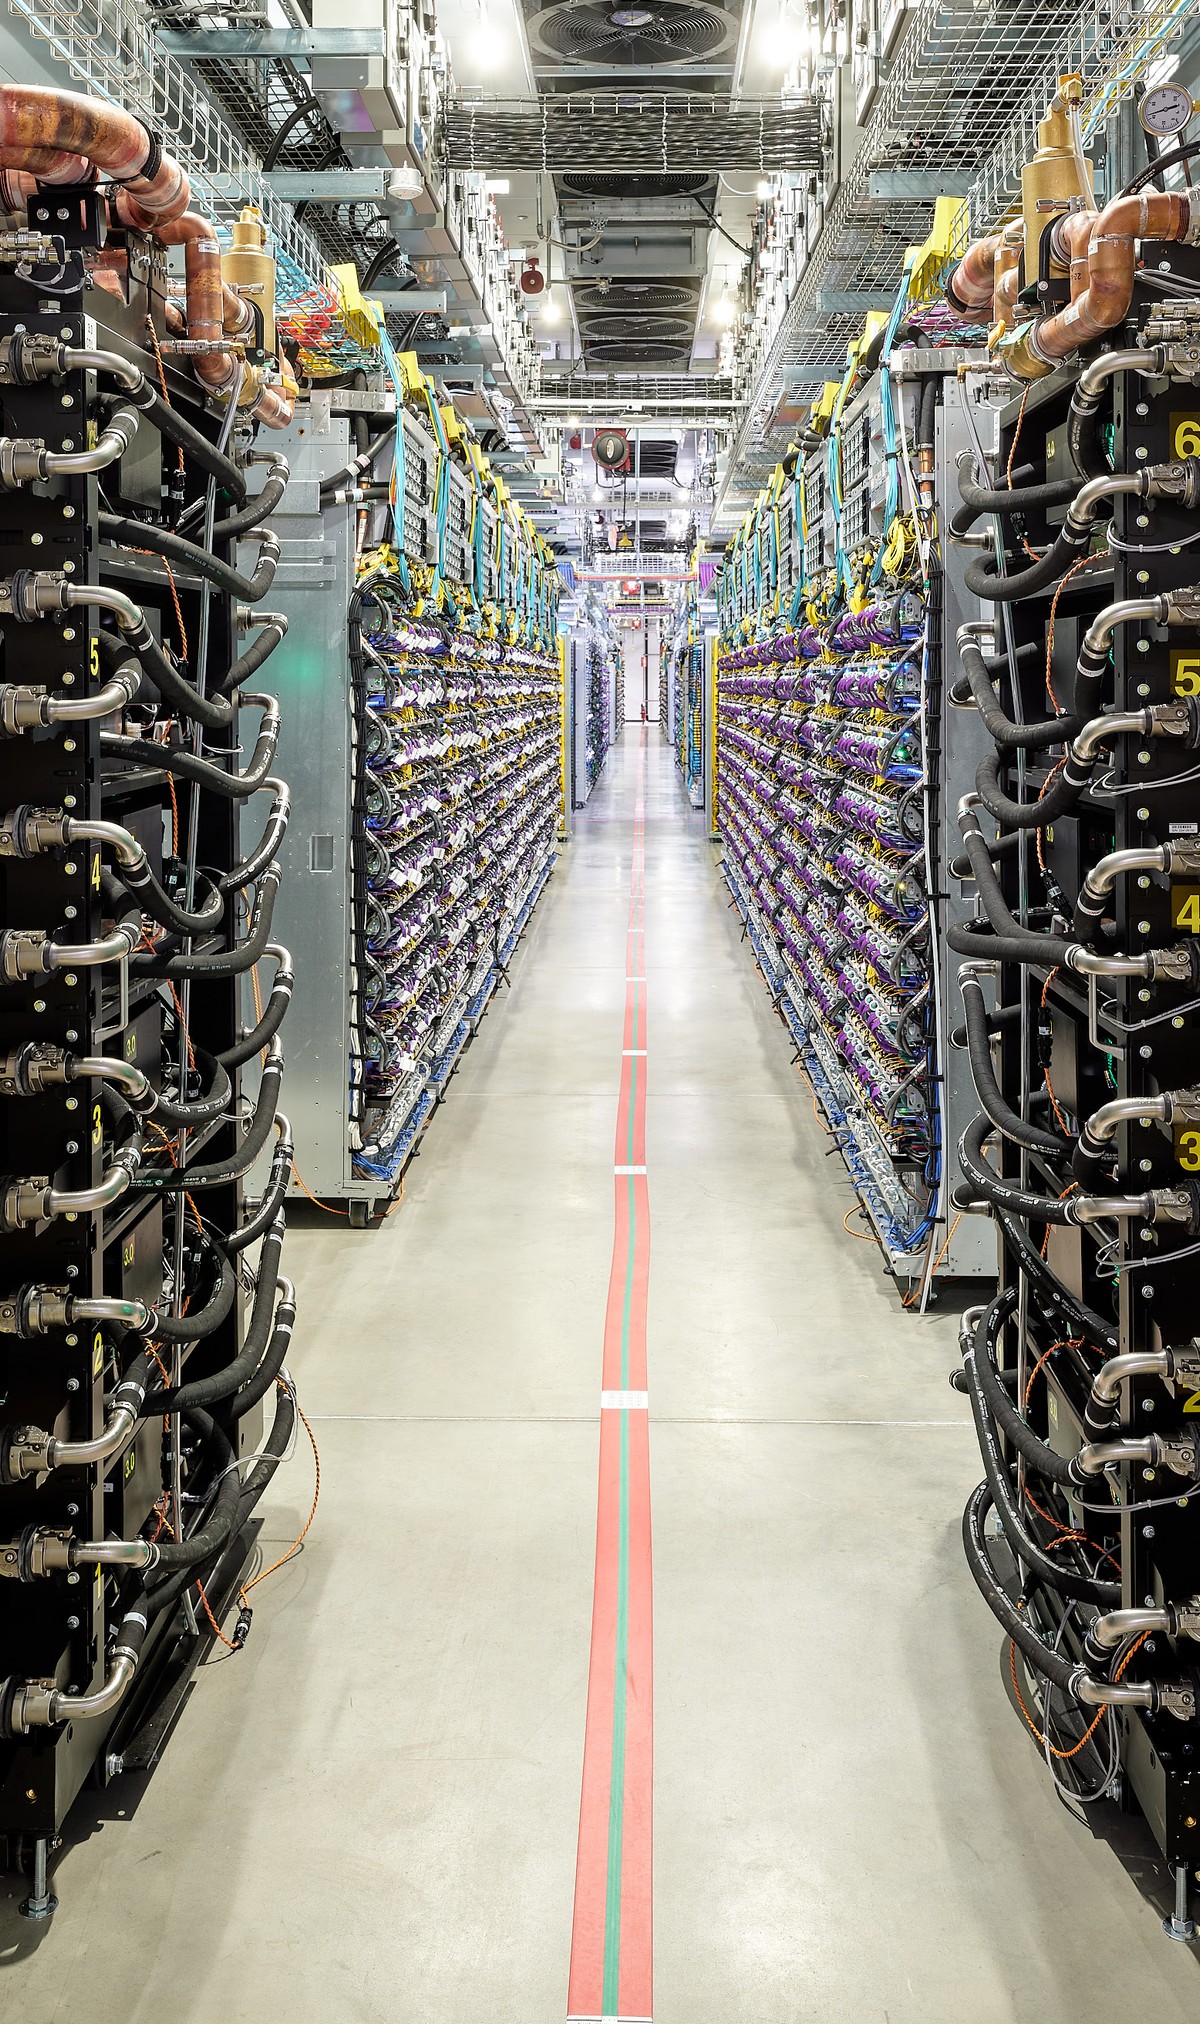
Confirmed by the engineer before you order.
Written by Diksha Shah, Principal AI Infrastructure Architect.⁴ Edwin Ozer answers for it too. Every mark, with its source, is in the comparison document.
Dell's network module and support hours, HPE's software support term, and NVIDIA's support hours.
Ask AI about this comparison: Claude · ChatGPT · Perplexity · Google AI Mode
Opens in a new tab with the question filled in.
Confirmed by the engineer before you order.
Written by Diksha Shah, Principal AI Infrastructure Architect.⁴ Edwin Ozer answers for it too. Every mark, with its source, is in the comparison document.
Dell's network module and support hours, HPE's software support term, and NVIDIA's support hours.
Ask AI about this comparison: Claude · ChatGPT · Perplexity · Google AI Mode
Opens in a new tab with the question filled in.